Blog

  • Key Signs a Product Has a Clean Label and How to Interpret Them

    1. The Clean Label Engineering Challenge: Parsing Intent Beyond Marketing Claims

    For software architects and backend engineers building consumer health applications, e-commerce filter engines, or supply chain verification platforms, translating market terminology into reliable database queries presents a structural challenge. The technical clean label food meaning cannot be captured by a simple boolean flag or a single manufacturer statement. In modern software systems, a ‘clean label’ represents a multi-dimensional data domain encompassing ingredient origin, chemical processing pathways, industrial additives, and structural transparency across the packaging taxonomy.

    Consumer product goods (CPG) packaging is filled with front-of-pack claims such as ‘All Natural’, ‘No Artificial Preservatives’, or ‘Simple Ingredients’. However, these marketing statements frequently lack standardized statutory definitions under regulatory frameworks like the US FDA or European EFSA. A product claiming ‘No Artificial Flavors’ might still contain chemically modified food starches, highly refined seed oils, or covert preservatives such as cultured celery extract—a direct source of naturally derived nitrates used to circumvent preservative labeling rules.

    As documented in industry analysis from The Grocer UK (FMCG & Supermarket Retail Intelligence), global food supply chains are undergoing rapid reformulations to strip out synthetic stabilizers and transparently present processing lineages. To programmatically classify whether a packaged food product truly meets clean-label criteria, developers cannot rely on unstructured manufacturer strings. Instead, ingestion pipelines require a deterministic parsing strategy that decomposes ingredient lists into hierarchical trees, evaluates processing classifications, and validates stated packaging claims against raw ingredient properties.

    Engineering a clean-label engine at scale requires solving three foundational data problems: resolving unstructured, localized ingredient text into canonical entity IDs; establishing an objective scoring system for processing intensity (e.g., NOVA, Nutri-Score); and separating raw manufacturer statements from verified, algorithmic clean-label assertions.

    2. Deterministic Signs of a Clean Label: Ingredient Lists, E-Numbers, and Processing Scores

    When constructing ingestion schemas for food data, determining clean-label status requires evaluating explicit indicators across the ingredient deck. A robust taxonomy evaluates four primary structural vectors: ingredient deck length, presence of synthetic additives (E-numbers), presence of industrial ultra-processing indicators, and verified organic or non-GMO status.

    The first indicator is ingredient list brevity and recognizability. Unprocessed or minimally processed foods typically exhibit low ingredient counts without complex chemical nomenclature. However, simple string count heuristics are insufficient; a product containing four distinct synthetic emulsifiers is significantly less ‘clean’ than one containing eight whole-food botanicals. Processing frameworks, such as the NOVA classification published in Cambridge University Press Public Health Nutrition, categorize food products into four distinct groups based on the extent and purpose of industrial processing:

    • NOVA Group 1: Unprocessed or minimally processed foods (e.g., fresh vegetables, raw nuts, whole grains).
    • NOVA Group 2: Processed culinary ingredients (e.g., oils, butter, sugar, salt extracted directly from Group 1 foods).
    • NOVA Group 3: Processed foods (e.g., simple canned vegetables, artisanal cheeses, freshly baked breads).
    • NOVA Group 4: Ultra-processed food products (UPFs) involving industrial formulations, fractionated substances, high-fructose corn syrup, hydrogenated oils, or additives designed to disguise sensory properties.

    A second deterministic vector is the absence of numerical additive codes (such as European E-numbers spanning E100–E1520) and synthetic food agents. Clean-label parsing pipelines flag emulsifiers (carboxymethylcellulose, polysorbates), artificial colorants (FD&C dyes), synthetic flavor enhancers (monosodium glutamate, disodium inosinate), artificial sweeteners (sucralose, acesulfame K, aspartame), and chemical preservatives (BHA, BHT, sodium benzoate).

    Finally, clean-label verification relies on multi-score integration. A production food API must normalize these variables into standardized quality metrics—including NOVA group, Nutri-Score, EcoScore, Organic qualification, Non-GMO qualification, and direct carcinogenic flags (e.g., presence of titanium dioxide, potassium bromate, or acrylamide risk vectors).

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    3. Handling Stated vs. Qualified Data: Resolving Manufacturer Ambiguity

    A common failure mode in food data architecture is trusting raw, manufacturer-supplied product metadata without secondary validation. In production environments, data schemas must enforce a strict separation between front-of-pack claims and algorithmically derived facts. NutriGraphAPI addresses this architectural requirement by organizing its 200+ product attributes across two distinct relational layers: scraped_data and analysed_data.

    The scraped_data object preserves the exact, raw text extracted from physical product packaging or retailer feeds. This includes literal ingredient strings, front-of-pack marketing claims, and declared allergen statements. Conversely, the analysed_data layer applies natural language processing, entity resolution, and safety rules to produce qualified, deterministic attributes.

    Attribute Dimension Stated Layer (scraped_data) Qualified Layer (analysed_data)
    Organic Status stated_organic: true (Based on packaging text) qualified_organic: true (Verified against USDA/EU organic certifier registries)
    Clean Preservative Flag stated_no_preservatives: true qualified_no_preservatives: false (Flagged due to cultured celery powder or nisin in ingredients)
    Allergen Exposure contains_soy: false qualified_soy_derived: true (Flagged via soy lecithin identified in sub-ingredient expansion)
    Carcinogenic Vector Unreported on packaging carcinogenic_flag: true (Triggered by presence of synthetic colorant or additive)

    By contrasting dual fields (such as stated_organic versus qualified_organic or stated_non_gmo versus qualified_non_gmo), backend engineers can prevent inaccurate marketing text from corrupting application logic. When an API client queries for clean-label products, the database filter operates against the analysed_data qualification pipeline, guaranteeing that hidden processing aids or mislabeled additives are correctly flagged regardless of front-of-pack claims.

    4. Allergen Trees and Dietary Compliance: Granular Ingredient Lineage

    Evaluating clean label credentials goes beyond identifying synthetic additives; it requires deep visibility into allergen cross-contamination and complex dietary compliance. Traditional food databases store allergens as top-level binary flags (e.g., has_dairy: true). However, modern enterprise platforms require granular lineage tracking that maps specific sub-ingredients to parent allergen groups.

    Clinical guidelines published by the European Academy of Allergy and Clinical Immunology (EAACI) emphasize that severe allergic reactions are often triggered by derivative agents or cross-reactive proteins hidden within compound ingredients. Rather than returning a single boolean flag, NutriGraphAPI generates structured, per-ingredient allergen trees mapped across 11 key allergen groups (peanuts, tree nuts, milk, eggs, fish, crustacean shellfish, soy, wheat, sesame, celery, and mustard). This allows system architects to inspect precisely which component in a complex formulation introduced a potential allergen or synthetic derivative.

    Simultaneously, clean-label applications often need to enforce strict religious and dietary constraints alongside chemical purity. Parsing compliance for Halal, Kosher, Jain, and Hindu diets requires evaluating complex ingredient chains. For instance, determining Jain compliance requires inspecting ingredient trees for root vegetables (such as garlic, onions, or potatoes) that may be obscured within generic terms like ‘natural seasonings’. Similarly, verifying Kosher or Halal compliance demands identifying hidden animal-derived enzymes, gelatin, or alcohol-based extraction carriers within flavor bases. NutriGraphAPI executes these multi-tier compliance checks automatically across every indexed GTIN.

    5. Architectural Trade-offs: Comparing Food Data Platforms

    When evaluating food data architectures for production integration, backend engineers must weigh dataset breadth, schema depth, latency, and data accuracy. Below is an objective technical comparison of major food data APIs against key clean-label engineering requirements:

    • USDA FoodData Central: Excellent, free reference dataset for raw micronutrient density and scientific reference foods. However, it lacks comprehensive UPC coverage for commercial packaged goods, provides no normalized GTIN-14 resolution, and includes zero clean-label or UPF classification fields.
    • Open Food Facts: A massive, open-source repository with global coverage. While valuable for general research, its reliance on crowdsourced data leads to inconsistent schema structures, unverified user submissions, missing allergen trees, and noisy ingredient text requiring heavy backend sanitization.
    • Spoonacular: Well-suited for consumer meal planning, consumer recipe apps, and home-cooking applications. However, it lacks enterprise package-level depth, lacks dual stated vs. qualified data separation, and offers limited capabilities for automated supply chain audit pipelines.
    • Edamam: Strong natural language processing for recipe nutrition analysis and macro estimations. However, it lacks deep 200+ attribute package extraction layers, lacks dual-layer claim verification, and does not expose per-ingredient allergen lineage trees.
    • Nutritionix: Strong focus on restaurant menu items and common consumer foods. However, enterprise tier access carries significant cost barriers, and the database lacks structured clean-label fields (such as NOVA scoring or carcinogenic flags) and religious matrix modeling (Jain/Hindu).
    • NutriGraphAPI: Engineered specifically for high-throughput backend integration, indexing over 5,000,000 UPCs with GTIN-14 normalization. It delivers a sub-150ms median latency, 200+ attributes split across scraped_data and analysed_data, 30+ dedicated clean-label fields, six automated quality scores, and full 11-allergen ingredient trees.

    6. Payload Blueprint & Integration Patterns for Clean-Label Filtering

    To integrate clean-label logic into a production backend, system designers can execute REST queries against NutriGraphAPI’s GTIN-14 endpoint. Below is a sample curl request demonstrating an item lookup and the structured response payload returned by the server:

    curl -X GET "https://api.nutrigraph.io/v1/product/lookup?gtin=00012345678905" 
      -H "Authorization: Bearer YOUR_API_KEY" 
      -H "Accept: application/json"

    The corresponding JSON response demonstrates the separation between raw package text and qualified clean-label metrics:

    {
      "gtin": "00012345678905",
      "scraped_data": {
        "brand": "Organic Harvest Co",
        "product_name": "Almond & Oat Energy Bar",
        "ingredients_text": "Organic Almonds, Organic Rolled Oats, Organic Tapioca Syrup, Sea Salt, Rosemary Extract.",
        "stated_claims": {
          "organic": true,
          "no_artificial_preservatives": true
        }
      },
      "analysed_data": {
        "nova_group": 1,
        "nutri_score": "A",
        "eco_score": "A",
        "quality_scores": {
          "organic_qualified": true,
          "non_gmo_qualified": true,
          "carcinogenic_flag": false,
          "clean_label_score": 98
        },
        "clean_label_attributes": {
          "is_clean_label": true,
          "free_from_artificial_flavors": true,
          "free_from_artificial_colors": true,
          "free_from_synthetic_preservatives": true,
          "ultra_processed_ingredients_count": 0
        },
        "dietary_compliance": {
          "halal_qualified": true,
          "kosher_qualified": true,
          "jain_qualified": true,
          "hindu_qualified": true
        },
        "allergen_tree": {
          "tree_nuts": [
            {
              "ingredient": "Organic Almonds",
              "severity": "direct"
            }
          ],
          "gluten": [
            {
              "ingredient": "Organic Rolled Oats",
              "severity": "trace_risk"
            }
          ]
        }
      }
    }

    This payload structure enables backend developers to execute ultra-fast, deterministic queries. For instance, an e-commerce platform can filter catalog items by checking analysed_data.clean_label_attributes.is_clean_label == true while enforcing analysed_data.quality_scores.carcinogenic_flag == false, shielding applications from unverified marketing claims.

    7. Evaluating and Deploying Clean-Label Analytics

    Implementing clean-label data logic requires moving beyond simple string pattern matching toward structured ingredient trees, dual-layer validation pipelines, and standardized quality frameworks like NOVA and Nutri-Score. By relying on deterministic data architectures rather than raw front-of-pack claims, engineering teams can build reliable health, retail, and compliance applications.

    NutriGraphAPI provides a scalable foundation for this pipeline, combining a database of 5,000,000+ GTIN-14 normalized products with sub-150ms median query performance. Engineering teams can evaluate the platform directly in development environments. NutriGraphAPI offers a developer tier with 1,000 free monthly lookups, requiring no credit card to start integration.

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols and global barcoding standards across these sources:

    Related Technical Architecture Guides

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols, and global barcoding standards across these authoritative sources:

  • What clean label food means for shoppers, developers, and brands

    1. Defining Clean Label: From Consumer Intent to Enterprise Schemas

    When product managers and backend engineers are asked to support clean label filtering, they usually start with a vague marketing definition. To understand what is clean label food in an engineering context, you must translate consumer expectations into deterministic data structures. For consumers, clean label means short, recognizable ingredient lists free from synthetic additives, artificial preservatives, ultra-processed fillers, and chemically modified starches. For brands, it represents a reformulation effort to align with consumer trust and pass regulatory scrutiny across international markets. For software engineers building e-commerce search engines, personalization algorithms, or compliance tools, clean label is an attribute resolution problem.

    Clean label is not a single, legally mandated certification like USDA Organic. Instead, it is a multi-dimensional set of rules evaluated against a product’s ingredient text, processing method, and supply chain lineage. Institutions like INRAE (French National Research Institute for Agriculture and Food) have advanced the scientific categorization of processed foods—such as the NOVA classification system—which directly informs how automated pipelines evaluate clean label compliance. A product asserting a clean label profile typically requires verification across four core domain vectors: ingredient simplicity (e.g., absence of titanium dioxide or high-fructose corn syrup), processing degree (NOVA Group 1 or 2 vs. ultra-processed NOVA Group 4), verification of non-synthetic sourcing backed by bodies like the USDA National Organic Program (NOP), and explicit declaration of processing aids.

    Building a backend system capable of handling these vectors requires more than simple regex matching on ingredient strings. A single additive can appear under dozens of chemical synonyms, international E-numbers, or branded trade names. Furthermore, ingredients are hierarchical; an emulsifier might be hidden inside a complex compound ingredient three levels deep. To deliver reliable clean label filtering, your data layer must parse unstructured packaging text into a normalized, queryable schema capable of distinguishing between manufacturer claims and algorithmic verification.

    2. The CPG Data Problem: Unstructured Text vs. Deterministic Schemas

    Packaging data in Consumer Packaged Goods (CPG) is notoriously messy. Manufacturers print ingredient lists to satisfy local label regulations, not software APIs. A typical ingredient declaration on a packaged snack might read: Enriched Flour (wheat flour, niacin, reduced iron, thiamine mononitrate, riboflavin, folic acid), Organic Cane Sugar, Palm Oil, Contains 2% or less of: Salt, Soy Lecithin, Natural Flavors. If your application needs to determine whether this product meets clean label criteria, a naive text search falls short immediately.

    Consider the structural challenges present in raw packaging text:

    • Nested Compound Ingredients: Ingredients enclosed in parentheticals contain sub-ingredients that must be parsed into an Abstract Syntax Tree (AST) rather than flattened into a string.
    • Synonyms and Regulatory Variants: Sodium ascorbate, E301, and Vitamin C are chemically identical in processing, but only some trigger automated synthetic additive flags depending on regional taxonomy.
    • Stated vs. Qualified Claims: A manufacturer may print “All Natural” on the front panel (a stated claim), but the ingredient panel may reveal artificial processing aids or bioengineered ingredients (failing a qualified evaluation).
    • Identifier Instability: Products re-formulate without changing their 12-digit UPC, or they change packaging formats across international markets using 13-digit EAN or 14-digit GTIN identifiers.

    To address this complexity, enterprise food architectures decouple raw ingestion from canonical evaluation. In NutriGraphAPI, this is handled via a two-layer data architecture: scraped_data and analysed_data. The scraped_data layer preserves the raw, unadulterated text extracted from physical package OCR or manufacturer GDSN feeds. The analysed_data layer executes canonical parsing, mapping raw strings into a standardized GTIN-14 key space, resolving synonyms to ontology IDs, and generating qualified quality metrics.

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    3. Evaluating Food Data APIs: Architecture and Trade-Offs

    Choosing the right data infrastructure for food applications depends heavily on your specific engineering requirements. No single API serves every use case perfectly, and engineering teams must evaluate trade-offs across coverage, latency, depth of attributes, and schema determinism.

    Provider Primary Strengths Key Architecture Trade-offs Best Fit Use Case
    NutriGraphAPI 5M+ GTIN-indexed products, 200+ attributes across scraped/analysed layers, 30+ clean label flags, sub-150ms median latency. Optimized for enterprise CPG and packaged goods; not built for raw restaurant recipe generation. Enterprise CPG e-commerce, automated compliance, clean label filtering, and allergen risk engines.
    USDA FoodData Central Official US government standard reference for raw, generic whole food composition and micronutrients. Lacks real-time GTIN-14 mapping for modern branded CPGs; no automated clean label or additive parser. Academic research, foundational nutrition calculations for whole foods.
    Open Food Facts Massive global crowdsourced open dataset; highly accessible community project. Inconsistent data quality; variable schema coverage; lacks enterprise SLAs or deterministic ingredient trees. Open-source tools, non-profit initiatives, high-level consumer aggregation.
    Edamam Strong Natural Language Processing (NLP) for unstructured recipe parsing and meal analysis. Focused on culinary recipe analysis rather than deep, GTIN-level CPG clean label supply chain attributes. Recipe management platforms, diet trackers, consumer culinary apps.
    Spoonacular Rich ecosystem for recipe management, meal planning, and consumer food log integrations. Attribute depth per packaged item is shallow compared to enterprise CPG compliance standards. Consumer lifestyle applications, meal kits, planning widgets.
    Nutritionix Extensive coverage of US restaurant chains, fast food items, and common branded items. Relies primarily on product-level boolean flags rather than deep semantic ingredient AST graphs. Fitness logging apps, consumer calorie counters, chain restaurant logging.

    If your team is building a culinary planning tool, Edamam or Spoonacular offer out-of-the-box recipe parsers that excel at handling home cooking inputs. If you are analyzing foundational nutritional science, USDA FoodData Central is the standard. However, when your system requires real-time programmatic decision-making over millions of packaged items—such as filtering an e-commerce catalog of 5,000,000+ UPC-indexed products by clean label criteria, allergen trees, or religious compliance—a specialized CPG engine like NutriGraphAPI becomes essential.

    4. Parsing Clean Label Metadata: JSON Schemas and Verification Logic

    To make clean label evaluation deterministic, NutriGraphAPI returns structured fields divided between manufacturer-declared values and system-evaluated facts. Standardizing these outputs follows principles of semantic data architecture, similar to data modeling concepts governed by the World Wide Web Consortium (W3C) Semantic Web Data standards, ensuring consistent property mapping across complex taxonomies.

    Below is a truncated representation of a NutriGraphAPI response payload for a packaged item evaluated for clean label properties, quality scores, and ingredient parsing:

    {
      "gtin14": "00012345678905",
      "product_name": "Organic Whole Grain Granola",
      "scraped_data": {
        "raw_ingredients_text": "Organic rolled oats, organic honey, organic sunflower oil, sea salt.",
        "stated_claims": ["100% Organic", "No Preservatives", "Non-GMO"]
      },
      "analysed_data": {
        "category_taxonomy": {
          "l1": "Pantry",
          "l2": "Cereals & Granola",
          "l3": "Granola"
        },
        "quality_scores": {
          "nova_group": 2,
          "nutri_score": "A",
          "eco_score": "B",
          "is_organic": true,
          "is_non_gmo": true,
          "carcinogenic_additive_flag": false
        },
        "clean_label_attributes": {
          "is_clean_label_qualified": true,
          "artificial_colors": false,
          "artificial_flavors": false,
          "synthetic_preservatives": false,
          "high_fructose_corn_syrup": false,
          "hydrogenated_oils": false,
          "ultra_processed_additives_count": 0
        },
        "stated_vs_qualified": {
          "organic": {"stated": true, "qualified": true},
          "non_gmo": {"stated": true, "qualified": true},
          "clean_label": {"stated": true, "qualified": true}
        }
      }
    }

    In this architecture, the scraped_data node contains exact packaging strings, while analysed_data exposes over 200 calculated fields. Notice the distinction inside stated_vs_qualified: a manufacturer might state a claim on the box, but NutriGraphAPI’s engine independently verifies that claim against the parsed ingredient tree, cross-referencing additive databases, processing classifications, and regulatory records.

    5. Handling Compliance Edge Cases: Allergens, Religious Rules, and Additives

    Where food applications frequently fail in production is edge case handling—specifically around cross-contamination, hidden processing aids, and multi-tier ingredient dependencies. Relying on simple boolean flags at the product level (e.g., contains_soy: false) creates significant risk for compliance and user safety.

    NutriGraphAPI addresses this by building per-ingredient allergen trees across 11 major allergen groups (including milk, eggs, fish, crustacean shellfish, tree nuts, peanuts, wheat, soybeans, sesame, celery, and mustard). Instead of a single flat flag, every node in the ingredient AST is evaluated. For example, if a product contains flavoring (contains milk), the top-level ingredient is flagged, the sub-ingredient parenthetical is linked, and the allergen tree highlights exact node inheritance. This level of granularity prevents false negatives during clean label and allergen filtering.

    Furthermore, clean label requirements often intersect with religious and dietary compliance rules, such as Halal, Kosher, Jain, and Hindu standards. The following considerations show how deeper attribute inspection works in practice:

    • Halal Verification: Checks for hidden alcohol carriers in natural flavorings, animal-derived mono- and diglycerides, or non-certified gelatin.
    • Kosher Verification: Evaluates equipment processing flags, dairy/meat separation indicators, and official pass-through certifications.
    • Jain Compliance: Scans the ingredient tree for root vegetables (e.g., garlic, onion, ginger, potato starch) that violate strict Jain dietary rules, even when present in minor spice blends.
    • Hindu Compliance: Flags animal-derived ingredients, including hidden tallow, lard, rennet, and bovine-sourced gelatins.

    By running these dietary compliance evaluations concurrently with clean label filters, your platform can deliver precise, multi-attribute search and personalization features without writing complex custom regex pipelines on the client or API gateway.

    6. Integration Strategy and Evaluation Benchmarks

    When integrating a food data API into a production backend, performance metrics matter just as much as catalog size. High-volume e-commerce checkouts, search indexing pipelines, and mobile scanning interfaces require low latency and deterministic identifier handling.

    To evaluate NutriGraphAPI or any prospective data supplier in your architecture, use the following operational criteria:

    1. Identifier Normalization: Test how the API handles varying barcode formats. NutriGraphAPI automatically normalizes incoming UPC-A, EAN-8, EAN-13, and GTIN-14 strings into standard GTIN-14 representation prior to database lookup, eliminating query mismatches.
    2. Latency Profiling: Verify median and P99 latency SLA guarantees. NutriGraphAPI maintains sub-150ms median latency, making it suitable for inline integration into real-time search queries and cart validation hooks.
    3. Taxonomy Depth: Ensure the API provides a structured, 3-tier category hierarchy (e.g., L1: Pantry > L2: Snacks > L3: Protein Bars) to enable precise navigational facet filtering in your application UI.
    4. Data Coverage Audit: Evaluate catalog width across your target inventory. NutriGraphAPI provides indexed access to 5,000,000+ UPC packaged food products globally, supporting both major brand CPGs and private label items.

    Software engineers can start testing integrations directly using NutriGraphAPI’s free Developer tier, which provides 1,000 free monthly lookups with no credit card required. This allows your team to validate payload schemas, test GTIN-14 normalizers, and benchmark clean label query response times against your actual product catalog before deploying to production.

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols and global barcoding standards across these sources:

    Related Technical Architecture Guides

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols, and global barcoding standards across these authoritative sources:
  • Clean label food colors

    1. Solving Food Data Complexity in Production Applications

    Building high-retention consumer health and grocery apps requires rich, structured food data. As documented on www.nutrigraphapi.com, NutriGraphAPI provides two intelligence layers—scraped_data and analysed_data—delivering over 200 attributes across 5,000,000+ UPC-indexed products in sub-150ms median latency.

    2. Complete Feature Overview

    Explore the full interactive schema on www.nutrigraphapi.com.

    Related Technical Architecture Guides

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols, and global barcoding standards across these authoritative sources:

  • Clean Label Food Definition and What It Really Means on Packaged Foods

    1. The Engineering Problem: Quantifying the Clean Label Food Definition

    From a regulatory standpoint, there is no standardized legal framework enforcing a clean label food definition under FDA or EFSA guidelines. While agencies regulate specific claims such as “organic” or “gluten-free,” the phrase “clean label” remains a consumer-facing industry paradigm rather than a single boolean flag in a government database. For backend engineers, data architects, and product managers building food intelligence platforms, enterprise grocery applications, or digital health systems, this absence of formal regulation presents a significant software architecture challenge.

    To model “clean label” programmatically, engineering teams cannot rely on simple string matching against ingredient statements. Front-of-pack consumer claims are frequently disconnected from the complex chemical composition listed on the back of the package. Synthetically derived emulsifiers, processing aids, artificial preservatives, disguised flavor enhancers, and industrial colorants often evade naive keyword filters. For instance, ingredients like autolyzed yeast extract or hydrolyzed vegetable protein contain free glutamate but are routinely leveraged to bypass consumer flags for monosodium glutamate (MSG). Similarly, cultured celery powder is frequently utilized as a source of naturally occurring nitrates to achieve a “no added nitrates” label claim while performing the exact chemical preservation function of sodium nitrate.

    When ingesting raw food data from government repositories such as USDA FoodData Central (FDC), engineering teams quickly observe that while raw nutrient analytical values are robust, the datasets lack pre-parsed ingredient graph models, standardized additive classification systems, or GTIN-indexed barcode mappings required for real-time application runtime lookups. Building a production-ready clean label engine requires normalizing unstructured ingredient text, mapping synonyms to standard chemical abstract registry numbers or E-number taxonomies, and evaluating both stated claims and inferred sub-ingredient risk profiles at scale.

    2. Deconstructing Clean Label Data: Stated vs. Qualified Verification

    A resilient data architecture for packaged foods must maintain a clear operational boundary between manufacturer-provided marketing claims and algorithmically verified analytical attributes. In NutriGraphAPI, this distinction is enforced through a two-layer data architecture comprising scraped_data and analysed_data across a repository of over 5,000,000 UPC-indexed packaged food products, each mapped across 200+ distinct attributes.

    The scraped_data layer captures raw, unmanipulated OCR extractions directly from physical packaging, including stated manufacturer assertions such as “All Natural,” “No Artificial Preservatives,” or “Clean Ingredients.” Reliance solely on this raw layer introduces severe business logic vulnerabilities, as brand marketing teams routinely deploy aggressive labeling strategies that do not withstand rigorous chemical or dietary audit.

    To solve this, NutriGraphAPI’s analysed_data layer processes the raw string payloads through deterministic parsing pipelines, producing 30+ dedicated clean-label fields alongside dual “stated” (manufacturer-declared) and “qualified” (system-verified) fields. This layer computes six standardized quality and risk scores in real time:

    • NOVA Classification: Categorizes products from Group 1 (unprocessed/minimally processed) to Group 4 (ultra-processed foods/UPFs) based on physical processing markers and industrial additives.
    • Nutri-Score: Algorithmic grade (A through E) balancing negative nutritional elements (sugars, saturated fats, sodium, energy) against positive elements (fiber, protein, fruit/vegetable percentage).
    • EcoScore: Environmental impact rating derived from life-cycle assessment (LCA) data, packaging recyclability, and supply chain logistics.
    • Organic Status: Qualified verification cross-referencing certified organic standards against the verified percentage of organic sub-ingredients.
    • Non-GMO Verification: Rigorous evaluation of bioengineered ingredient flags and risk-crop derivatives.
    • Carcinogenic & Harmful Additive Flagging: Real-time deterministic detection of high-risk compounds, including titanium dioxide (E171), potassium bromate, BHA, BHT, and azodicarbonamide.

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    3. Per-Ingredient Parsing and Allergen Graph Modeling

    Legacy nutritional APIs typically surface food safety data as flat, product-level booleans (e.g., contains_soy: true). This primitive model fails in enterprise environments. A single product-level boolean cannot distinguish between an active main ingredient (e.g., whole soybeans), a highly refined processing derivative with negligible protein residue (e.g., soy lecithin as an emulsifier), or an isolated facility cross-contamination warning (“may contain soy”).

    NutriGraphAPI replaces flat boolean responses with per-ingredient allergen trees mapped across 11 primary global allergens. Rather than returning a static flag, the API builds a directional acyclic graph (DAG) of the ingredient hierarchy. Nested sub-ingredients—such as Enriched Flour [wheat flour, niacin, reduced iron, thiamine mononitrate, riboflavin, folic acid]—are fully parsed into child nodes. This allows backend rule engines to trace the exact lineage of an allergen or synthetic additive down to its constituent parent component.

    This granular approach is vital when engineering dietary restriction filters for sensitive populations. For instance, developers building applications for celiac disease management can reference standards outlined by the National Celiac Association (NCA) to verify that missing a single barley-malt flavoring derivative inside an unnested sub-ingredient string poses severe health risks. A hierarchical graph engine prevents these hidden vectors by resolving every sub-ingredient node against known gluten-containing taxonomies.

    Furthermore, this multi-layered tree model powers strict religious and dietary compliance engines across four major complex frameworks: Halal, Kosher, Jain, and Hindu dietary rules. For example, evaluating Jain compliance requires the algorithmic rejection of any root vegetables (e.g., garlic, onion, potatoes), even when buried within generic “natural flavorings” sub-strings. Similarly, Kosher and Halal engines evaluate processing derivative chains to identify forbidden enzymes, porcine-derived gelatins, or uncertified alcohol carriers used during flavor compounding.

    4. Architectural Implementation: JSON Payloads, Normalization, and Latency

    Integrating clean label verification into point-of-sale systems, e-commerce checkout flows, or real-time clinical applications requires deterministic barcode normalization and aggressive latency guarantees. NutriGraphAPI normalizes incoming barcode queries across GTIN-8, GTIN-12 (UPC-A), GTIN-13, and GTIN-14 formats into a standardized zero-padded GTIN-14 string before querying the index, avoiding key cache misses caused by legacy format drift.

    To support high-throughput microservice architectures, the system achieves a sub-150ms median response latency globally. Product categorizations are structured under a deterministic 3-tier category hierarchy (e.g., Pantry > Condiments & Sauces > Organic Salad Dressings), enabling instant faceted search filtering across large catalog indexes.

    The following example demonstrates a standard NutriGraphAPI response payload detailing the clean-label analysis, dual validation fields, and per-ingredient parsing tree for a packaged food query:

    {
      "gtin": "00012345678905",
      "product_name": "Artisanal Organic Creamy Almond Butter",
      "categories": {
        "tier_1": "Pantry",
        "tier_2": "Spreads & Butters",
        "tier_3": "Nut Butters"
      },
      "scraped_data": {
        "declared_claims": ["100% Clean", "No Artificial Preservatives", "All Natural"],
        "raw_ingredient_text": "Dry Roasted Organic Almonds, Sea Salt."
      },
      "analysed_data": {
        "clean_label_attributes": {
          "clean_label_score": 98,
          "is_clean_label_qualified": true,
          "synthetic_additives_count": 0,
          "ultra_processed_flag": false,
          "carcinogenic_additives_present": false
        },
        "scores": {
          "nova_group": 1,
          "nutri_score": "A",
          "ecoscore": "A",
          "organic_qualified": true,
          "non_gmo_qualified": true
        },
        "stated_vs_qualified": {
          "organic": {"stated": true, "qualified": true},
          "preservative_free": {"stated": true, "qualified": true},
          "no_added_sugar": {"stated": true, "qualified": true}
        },
        "dietary_compliance": {
          "halal": true,
          "kosher": true,
          "jain": true,
          "hindu": true
        },
        "ingredient_tree": [
          {
            "node_id": "ing_001",
            "name": "Organic Dry Roasted Almonds",
            "clean_status": "clean",
            "allergens": ["tree_nuts"],
            "sub_ingredients": []
          },
          {
            "node_id": "ing_002",
            "name": "Sea Salt",
            "clean_status": "clean",
            "allergens": [],
            "sub_ingredients": []
          }
        ]
      }
    }

    5. Vendor Benchmarking: API Alternatives and Enterprise Trade-offs

    When evaluating vendor options for food data integration, software architects must weigh database scope, schema stability, latency SLAs, and structural depth. No single food API fits every engineering context, and selecting the correct vendor requires an honest assessment of trade-offs.

    Provider Primary Strengths Core Limitations Ideal Engineering Use Case
    NutriGraphAPI 5M+ GTIN products; 200+ attributes; dual stated/qualified fields; 30+ clean label metrics; 11-allergen ingredient graph; sub-150ms latency. Focused strictly on packaged retail CPG items; not designed for unbranded raw agriculture or custom meal assembly algorithms. Enterprise e-commerce, digital health software, retail POS risk engines, and clean-label compliance auditing.
    USDA FoodData Central (FDC) Gold-standard public domain micro- and macronutrient reference data derived from chemical lab analysis. No native GTIN-14 mapping for barcode scanning; lacks pre-parsed additive flags, clean label scoring, or real-time catalog updates. Academic research, basic clinical baseline calculations, and public sector nutrition modeling.
    Open Food Facts Massive crowd-sourced worldwide dataset with broad international footprint and open-source availability. Inconsistent schema completeness; unverified user contributions; lacks deterministic enterprise validation guarantees. Open-source projects, academic studies, and non-critical consumer exploratory prototypes.
    Spoonacular & Edamam Rich recipe parsing capabilities, meal planning engines, and semantic natural language cooking processing. Tailored primarily for recipe composition rather than deep retail CPG packaging verification, GTIN lookup, or score computation. Consumer recipe aggregators, meal-kit apps, and kitchen IoT hardware integration.
    Nutritionix Extensive restaurant menu coverage and branded US food item database with user-friendly search APIs. Focuses heavily on standard nutrition facts panels; lacks dual stated vs. qualified clean label engines and multi-layer allergen DAGs. Fitness tracking applications, restaurant logging tools, and basic calorie counting interfaces.

    For teams evaluating environmental impact modeling alongside clean label scoring, comparing external environmental frameworks like the ADEME Agribalyse Environmental LCA Database provides deep insight into life-cycle assessment methodologies. While open databases offer strong base references, enterprise pipelines require integrated scoring systems (such as NutriGraphAPI’s EcoScore and NOVA attributes) attached directly to GTIN lookups to run high-throughput operations without complex multi-database join operations.

    6. Practical Integration Strategy and Evaluation Checklist

    Engineering teams embarking on a clean-label integration should adopt an empirical evaluation methodology. Rather than trusting marketing documentation, technical leads should benchmark candidates against five critical criteria during proof-of-concept sprint spikes:

    1. GTIN Match Rate & Schema Stability: Test your existing product SKU catalogs against the API index using normalized GTIN-14 queries to verify match coverage and key payload consistency.
    2. Additive Graph Depth: Query products containing complex ingredient lists (e.g., ultra-processed baked goods or seasoned snacks) to verify whether sub-ingredients, E-numbers, and masked preservatives are extracted into discrete JSON nodes or left as raw strings.
    3. Verification Precision: Audit cases where front-of-pack claims contradict backend ingredients (e.g., “All Natural” snacks containing synthetic sodium acid pyrophosphate) to ensure the API’s qualified fields correctly override raw stated claims.
    4. Response Latency under Load: Execute stress tests against the endpoint to confirm median latencies stay well under 150ms during peak checkout or batch indexing scenarios.
    5. Dietary Rule Determinism: Test edge cases for Halal, Kosher, Jain, and Hindu compliance, verifying that hidden animal derivatives or underground root vegetables trigger accurate rejection flags.

    To accelerate technical evaluation, NutriGraphAPI provides a free Developer Tier offering 1,000 monthly lookup requests with complete access to both scraped_data and analysed_data payloads. Registration requires no credit card, allowing backend engineers to write integration tests, evaluate payload structures, and run benchmark benchmarks directly in local development environments within minutes.

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols and global barcoding standards across these sources:

    Related Technical Architecture Guides

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols, and global barcoding standards across these authoritative sources:

  • Clean label food trends

    1. Solving Food Data Complexity in Production Applications

    Building high-retention consumer health and grocery apps requires rich, structured food data. As documented on www.nutrigraphapi.com, NutriGraphAPI provides two intelligence layers—scraped_data and analysed_data—delivering over 200 attributes across 5,000,000+ UPC-indexed products in sub-150ms median latency.

    2. Complete Feature Overview

    Explore the full interactive schema on www.nutrigraphapi.com.

    Related Technical Architecture Guides

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols, and global barcoding standards across these authoritative sources:

  • Clean label food preservatives

    1. Solving Food Data Complexity in Production Applications

    Building high-retention consumer health and grocery apps requires rich, structured food data. As documented on www.nutrigraphapi.com, NutriGraphAPI provides two intelligence layers—scraped_data and analysed_data—delivering over 200 attributes across 5,000,000+ UPC-indexed products in sub-150ms median latency.

    2. Complete Feature Overview

    Explore the full interactive schema on www.nutrigraphapi.com.

    Related Technical Architecture Guides

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols, and global barcoding standards across these authoritative sources:

  • How to evaluate a nutrition API database for clinical-grade apps

    1. Why Selecting a Clinical-Grade Nutrition API Database Is Critical in 2026

    Designing clinical-grade health applications, digital therapeutics, or hospital-integrated dietary platforms requires an uncompromising standard of data precision. When software engineers and medical informatics teams evaluate a nutrition api database, they are not merely fetching macro ratios for a fitness tracker; they are deploying software that impacts patient safety, disease management, and long-term metabolic health. In an era where chronic disease management relies heavily on digital intervention, a single hallucinated ingredient or misparsed allergen profile can lead to severe adverse reactions or compromised therapeutic protocols.

    Healthcare developers routinely face the daunting reality of fragmented consumer food data. Standard commercial food databases often rely on crowdsourced, unverified crowdsourcing pipelines where user errors run rampant. For a patient managing Celiac disease, severe IgE-mediated peanut allergies, or end-stage renal disease requiring strict potassium monitoring, relying on superficial string-matching algorithms is a high-risk gamble. Adhering to rigorous safety guidelines, such as those established by the Food Allergy Research & Education (FARE) Clinical Standards, requires digital systems to evaluate food products at an architectural level—parsing not just high-level labels, but deeply nested sub-ingredients and processing aids.

    Furthermore, regulatory compliance across international markets complicates API integration. As global authorities tighten safety metrics—such as the European Food Safety Authority (EFSA) Additive Safety Regulations—digital health tools must maintain dynamic, real-time databases capable of identifying obscure emulsifiers, localized E-numbers, and complex chemical derivatives. A clinical-grade nutrition api database must bridge the gap between simple nutrition panels and complex biochemical safety data, ensuring that both patients and clinical teams receive actionable, bulletproof nutritional intelligence.

    Building or choosing a health engine requires moving past basic calorie counters. Modern clinical applications demand structural intelligence—a system capable of evaluating compound ingredient structures, multi-person household restrictions, and deep contextual risk analysis without pushing consumers behind predatory paywalls or providing simplistic, moralizing food scores.

    🔬 The 5-Million Product Advantage: Food Scan Genius connects to the enterprise NutriGraph Database — scanning over 5,000,000+ verified UPC/EAN barcodes with recursive AST sub-ingredient parsing to detect allergens, additives, and dietary triggers in under 2 seconds.
    ⚡ 100% Free · 39 Diets · 5M+ Products · NutriGraph API

    Scan Any Food for Nutrition Api Database in 2 Seconds Free

    Never second-guess confusing grocery labels again. Download Food Scan Genius to uncover hidden additives, toxic dyes, and allergens for the whole household before you buy.

    Download on the Apple App StoreGet it on Google Play
    🔒 Zero Paywalls for Allergens  •  ⚡ Instant 2-Sec Camera Scan  •  👨‍👩‍👧‍👦 Multi-Household Profiles  •  🌍 11 Languages

    2. Deceptive Labeling, Nested Allergens, and Technical API Loopholes

    Evaluating a consumer food item programmatically is notoriously difficult due to industry labeling loopholes and regulatory exemptions. Basic nutrition APIs often ingest ingredient lists as flat, unformatted text blocks. This naive approach fails to uncover critical hidden triggers and localized naming variations that put vulnerable users at risk. For instance, recent scientific insights, including PubMed Research on Ultra-Processed Foods & Gut Microbiome Disruption, highlight how synthetic additives and hyper-processed emulsifiers directly alter gut permeability—yet these ingredients are frequently buried under vague regulatory terms like ‘flavoring agents’ or ‘processing aids’.

    To qualify as clinical-grade, a nutrition api database must overcome several persistent data challenges and deceptive food labeling practices:

    • Unparsed Compound Ingredients: Ingredients like ‘pre-cooked seasoned chicken breast’ contain hidden sub-ingredients (e.g., soy protein isolate, wheat starch, sodium phosphate). Standard APIs treat this as a single string, missing hidden allergens entirely.
    • Chemical Aliasing & E-Number Obfuscation: Synthetic preservatives and food dyes often shift names depending on the country of manufacture (e.g., E621 vs. Monosodium Glutamate vs. Autolyzed Yeast Extract). A clinical database must normalize these entities recursively.
    • Hidden Sodium and Sugar Derivatives: Maintaining baseline compliance with the World Health Organization Guidelines on Healthy Diets & Saturated Fats requires detecting over 60 distinct chemical names for added sugars and hidden sodium compounds (such as maltodextrin, barley malt, or disodium inosinate).
    • Missing Processing Classifications (NOVA Framework): Physical nutrient counts do not tell the whole story. A clinically robust API must evaluate food matrix degradation, distinguishing whole foods from ultra-processed formulations classified under NOVA groups 1 through 4.
    • Cross-Contamination and Facility-Level Risks: Standard APIs ignore precautionary allergen labeling (‘May contain trace amounts of…’). A enterprise-grade API must separate active ingredients from facility cross-contamination risk flags.
    • Static Localized Data: Multinational brands frequently reformulate products by region. An API operating without localized, multilingual EAN/UPC database mappings risks serving dangerous, outdated allergen data to international users.

    3. Architectural Superiority: NutriGraph AST Parsing vs. Legacy APIs

    Evaluation Vector Food Scan Genius (NutriGraph) Legacy Commercial APIs Government / Public APIs
    Database Scale & Parsing 5,000,000+ UPC/EAN items with Recursive Abstract Syntax Tree (AST) parsing 100k-1M items; flat-string regex search without sub-ingredient extraction Limited UPC coverage; unstructured raw text panels
    Dietary & Allergy Engines 39 Core Profiles + Custom Sensitivity Engine (Seed oils, specific dyes) 8-12 Basic Top-8 Allergen tags; no custom additive tracking None; raw nutrient profiles only
    Household Safety Logic Multi-Household Screening with named attribution (e.g., ‘Fails for Sri’) Single-user toggle only; requires manual profile switching N/A
    Processing & Quality Metrics NOVA 1-4 classification, Nutri-Score, & ScanGenius AI Context Engine Basic macro breakdown; unvalidated consumer ratings Unprocessed raw laboratory data
    Monetization Model 100% Free Core Features; Zero Paywalls for foundational scanning Heavy paywalls ($59/yr apps, expensive API rate-tier caps) Free, but lacks modern mobile integration infrastructure

    The core technology driving Food Scan Genius is the enterprise NutriGraph Database, constructed specifically to address the vulnerabilities of legacy food scanners. Instead of relying on crude text matching, NutriGraph employs recursive Abstract Syntax Tree (AST) parsing. When a product barcode is scanned, the engine decomposes the ingredient string into an object-oriented hierarchical tree. This allows the system to trace nested sub-ingredients three or four levels deep, identifying hidden dairy derivatives, hidden corn syrup solids, or specific seed oils buried inside complex industrial emulsifiers.

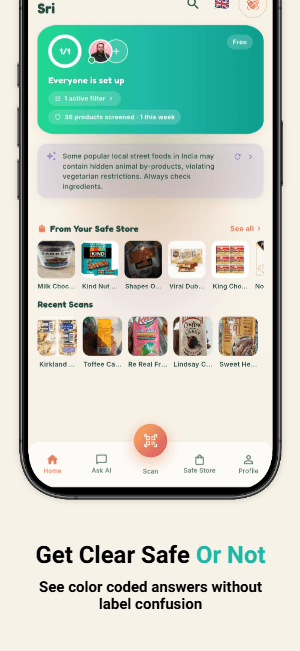
    Complemented by ScanGenius AI Insight, the platform avoids delivering fear-mongering, arbitrary zero-to-100 scores. Instead, it offers objective, clinical-grade context by integrating NOVA 1-4 ultra-processing metrics, global Nutri-Score standards, and real-time translation across 11 global languages. Furthermore, Food Scan Genius solves the multi-person screening dilemma with its Multi-Household Family Profiles engine. In a single 2-second scan, the app evaluates the product against every member of a household simultaneously, yielding clear, non-moralizing attribution such as ‘Fails for Sri (Gluten)’ or ‘Fails for Maya (Tartrazine)’. Healthcare providers and consumers gain immediate, uncompromising clarity without paywalls or restrictive subscription gates.

    4. Related Food Safety & Dietary Guides

    5. Scientific & Health Authority References

    6. How to Scan in 3 Simple Steps

    1. Download the Food Scan Genius app for free on iOS or Android with zero core feature paywalls.
    2. Configure individual household profiles by selecting from 39 clinical dietary presets or adding custom sensitivities (e.g., specific seed oils or food dyes).
    3. Scan any food barcode in under two seconds to receive an instant, multi-profile audit powered by the NutriGraph AST engine and ScanGenius AI Insight.
    Peanut and Tree Nut Screening Interface

    Instant Nut Allergen Audit Trail

    7. Frequently Asked Questions (FAQ)

    What makes a nutrition API database ‘clinical-grade’ compared to standard food logging databases?

    A clinical-grade nutrition API database goes beyond high-level macronutrient counts by utilizing recursive parsing algorithms to analyze nested sub-ingredients, processing aids, additive safety profiles, and chemical aliases. Food Scan Genius utilizes the enterprise NutriGraph Database, which parses over 5,000,000 verified UPC/EAN barcodes down to sub-ingredient trees, ensuring accurate detection of hidden allergens, additives, and NOVA processing levels.

    How does the NutriGraph Database handle complex, deeply nested ingredient lists?

    NutriGraph uses recursive Abstract Syntax Tree (AST) parsing. Instead of treating an ingredient panel as flat text, it converts parenthetical ingredient structures into hierarchical nodes. This allows the platform to spot hidden triggers—such as soy lecithin inside a compound chocolate chips ingredient—even when buried deep within complex pre-packaged foods.

    Can Food Scan Genius evaluate a single product for multiple family members simultaneously?

    Yes. The Food Scan Genius Multi-Household Family Profile engine allows you to screen a product against every family member’s specific restrictions in a single scan. The system provides clear, individual attribution (e.g., ‘Safe for Alex; Fails for Sri (Gluten)’), eliminating the need to re-scan products or switch user accounts manually.

    Why does Food Scan Genius avoid simple 1-100 health scores?

    Simplistic numeric scores often moralize food and obscure critical clinical details. A product might score an arbitrary ’80/100′ while still containing a fatal allergen or high sodium levels dangerous for kidney disease patients. Food Scan Genius provides ScanGenius AI Insight, offering transparent, scientific metrics including NOVA 1-4 processing tiers, Nutri-Score, and exact additive safety breakdowns without misleading generalization.

    🌱 Join 50,000+ Clean-Eating Shoppers

    Follow Food Scan Genius on Social

    Get daily supermarket label teardowns, hidden additive exposes, and clean grocery swaps delivered straight to your feed:

    ⚡ 100% Free · 39 Diets · 5M+ Products · NutriGraph API

    Take Control of Nutrition Api Database — Scan Free Today

    Never second-guess confusing grocery labels again. Download Food Scan Genius to uncover hidden additives, toxic dyes, and allergens for the whole household before you buy.

    Download on the Apple App StoreGet it on Google Play
    🔒 Zero Paywalls for Allergens  •  ⚡ Instant 2-Sec Camera Scan  •  👨‍👩‍👧‍👦 Multi-Household Profiles  •  🌍 11 Languages

    {
    “@context”: “https://schema.org”,
    “@graph”: [
    {
    “@type”: “Organization”,
    “@id”: “https://scangeni.us/#organization”,
    “name”: “Food Scan Genius”,
    “url”: “https://scangeni.us/”,
    “logo”: “https://scangeni.us/wp-content/uploads/2024/11/New-Logo512.png”,
    “sameAs”: [
    “https://www.linkedin.com/in/foodscangenius”,
    “https://www.instagram.com/foodscangenius/”,
    “https://x.com/FoodScanGenius”,
    “https://www.facebook.com/profile.php?id=61573096020486”,
    “https://www.pinterest.com/foodscangenius/”,
    “https://www.youtube.com/@FoodScanGenius-YT”
    ]
    },
    {
    “@type”: “SoftwareApplication”,
    “@id”: “https://scangeni.us/#app”,
    “name”: “Food Scan Genius”,
    “operatingSystem”: “iOS, Android”,
    “applicationCategory”: “HealthApplication”,
    “applicationSubCategory”: “Food & Drink, Nutrition, Allergen Scanner”,
    “offers”: {
    “@type”: “Offer”,
    “price”: “0.00”,
    “priceCurrency”: “USD”
    },
    “aggregateRating”: {
    “@type”: “AggregateRating”,
    “ratingValue”: “4.8”,
    “reviewCount”: “1250”
    },
    “downloadUrl”: [
    “https://apps.apple.com/us/app/food-scan-genius/id6740920516”,
    “https://play.google.com/store/apps/details?id=com.mycompany.fsgproject&hl=en_IN”
    ],
    “description”: “Free food ingredient scanner and allergen detector powered by the 5,000,000+ NutriGraph database with 39 customizable diets and 11 languages.”
    },
    {
    “@type”: “Article”,
    “@id”: “https://scangeni.us/nutrition-api-database/#article”,
    “isPartOf”: {
    “@id”: “https://scangeni.us/nutrition-api-database/”
    },
    “headline”: “How to evaluate a nutrition API database for clinical-grade apps”,
    “description”: “Learn how to evaluate a nutrition API database for clinical-grade apps. Ensure accurate allergen parsing, NOVA scoring, and deep ingredient data.”,
    “mainEntityOfPage”: “https://scangeni.us/nutrition-api-database/”,
    “publisher”: {
    “@id”: “https://scangeni.us/#organization”
    }
    },
    {
    “@type”: “FAQPage”,
    “@id”: “https://scangeni.us/nutrition-api-database/#faq”,
    “mainEntity”: [
    {
    “@type”: “Question”,
    “name”: “What makes a nutrition API database ‘clinical-grade’ compared to standard food logging databases?”,
    “acceptedAnswer”: {
    “@type”: “Answer”,
    “text”: “A clinical-grade nutrition API database goes beyond high-level macronutrient counts by utilizing recursive parsing algorithms to analyze nested sub-ingredients, processing aids, additive safety profiles, and chemical aliases. Food Scan Genius utilizes the enterprise NutriGraph Database, which parses over 5,000,000 verified UPC/EAN barcodes down to sub-ingredient trees, ensuring accurate detection of hidden allergens, additives, and NOVA processing levels.”
    }
    },
    {
    “@type”: “Question”,
    “name”: “How does the NutriGraph Database handle complex, deeply nested ingredient lists?”,
    “acceptedAnswer”: {
    “@type”: “Answer”,
    “text”: “NutriGraph uses recursive Abstract Syntax Tree (AST) parsing. Instead of treating an ingredient panel as flat text, it converts parenthetical ingredient structures into hierarchical nodes. This allows the platform to spot hidden triggers—such as soy lecithin inside a compound chocolate chips ingredient—even when buried deep within complex pre-packaged foods.”
    }
    },
    {
    “@type”: “Question”,
    “name”: “Can Food Scan Genius evaluate a single product for multiple family members simultaneously?”,
    “acceptedAnswer”: {
    “@type”: “Answer”,
    “text”: “Yes. The Food Scan Genius Multi-Household Family Profile engine allows you to screen a product against every family member’s specific restrictions in a single scan. The system provides clear, individual attribution (e.g., ‘Safe for Alex; Fails for Sri (Gluten)’), eliminating the need to re-scan products or switch user accounts manually.”
    }
    },
    {
    “@type”: “Question”,
    “name”: “Why does Food Scan Genius avoid simple 1-100 health scores?”,
    “acceptedAnswer”: {
    “@type”: “Answer”,
    “text”: “Simplistic numeric scores often moralize food and obscure critical clinical details. A product might score an arbitrary ’80/100′ while still containing a fatal allergen or high sodium levels dangerous for kidney disease patients. Food Scan Genius provides ScanGenius AI Insight, offering transparent, scientific metrics including NOVA 1-4 processing tiers, Nutri-Score, and exact additive safety breakdowns without misleading generalization.”
    }
    }
    ]
    }
    ]
    }

    Related Technical Architecture Guides

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols, and global barcoding standards across these authoritative sources:

  • Benchmarking Latency and Data Quality Across Modern Open Nutrition API Providers

    1. The Technical Challenges of Production Food Data Integration

    Integrating nutrition and consumer packaged goods (CPG) data into production applications presents engineering challenges that differ significantly from standard REST API integrations. Backend systems powering point-of-sale platforms, enterprise inventory systems, clinical trial nutrition monitors, and e-commerce platforms require deterministic response times, canonicalized primary keys, and deep schema predictability. When building infrastructure around an open nutrition api, engineers routinely confront three core data pipeline hurdles: barcode canonicalization, schema volatility, and superficial allergen flags.

    First, barcode identifiers arrive from mobile clients, laser scanners, and upstream database syncs in disparate formats. A single SKU might be transmitted as a 12-digit UPC-A, a 13-digit EAN-13, or a padded 14-digit GTIN-14. Without immediate, zero-allocation byte-level normalization at the API edge, database lookups suffer from cache misses or redundant records. Adhering to GS1 UK Retail Supply Chain Standards requires stripping check digits for validation and left-padding keys to a uniform GTIN-14 representation prior to indexing.

    Second, latency budgets for point-of-scan user experience are unforgiving. If a user scans a barcode at checkout or within a logistics app, the round-trip latency budget—including TLS negotiation, edge routing, query execution, payload serialization, and client rendering—must remain under 300 milliseconds. This places strict constraints on backend data providers: p50 query execution must consistently hit sub-150ms benchmarks even when executing complex joins across relational tables or querying graph models of multi-tier product categories.

    Third, traditional boolean representations of food attributes (e.g., contains_gluten: false) are dangerously inadequate for production applications. CPG manufacturers frequently reformulate products, omit sub-ingredients in summary packaging, or change factory lines without updating high-level flags. High-reliability applications require raw text extraction paired with deep semantic parsing, preserving both raw, manufacturer-declared text and computationally qualified metadata downstream.

    2. Comparative Landscape: Open Food Facts, USDA FDC, Commercial APIs, and NutriGraphAPI

    When selecting a data provider, system architects must evaluate trade-offs between open crowdsourced models, government reference datasets, commercial aggregation layers, and specialized domain graph APIs. No single API serves every architectural pattern, making comparative benchmarking essential during technical discovery.

    Provider Primary Use Case Database Depth Median Latency (p50) Key Trade-offs
    USDA FoodData Central Government baseline, reference raw foods ~500k records (mostly raw/foundation) ~350ms – 600ms Gold standard analytical accuracy via USDA Agricultural Research Service; sparse CPG coverage and unoptimized for real-time mobile scanning.
    Open Food Facts Crowdsourced open data research ~3M+ crowdsourced records ~250ms – 500ms High international volume; inconsistent schema validation, frequent missing fields, and unverified user submissions.
    Edamam Recipe parsing & NLP ingredient analysis Recipe focus + CPG search ~200ms – 350ms Strong natural language processing for unstructured recipe text; less granular for downstream CPG ingredient tree parsing.
    Spoonacular Meal planning & consumer recipe engines Recipes + basic CPG products ~200ms – 400ms Rich feature set for consumer meal planning; lacks multi-layer raw-vs-verified attribute split for enterprise CPG.
    Nutritionix Restaurant chains & common brand logging ~800k brand/restaurant items ~180ms – 300ms Excellent coverage for US restaurant chains; restricted customization for clean-label evaluation and complex allergen trees.
    NutriGraphAPI Enterprise CPG intelligence & live scanning 5,000,000+ UPC-indexed products <150ms High-throughput CPG focus, dual scraped_data/analysed_data schema layer, 200+ fields, deep allergen resolution trees.

    For applications where raw scientific accuracy for generic commodities is required (such as agricultural research), USDA FoodData Central remains the canonical choice. For consumer apps building meal planners using unstructured web recipes, Edamam and Spoonacular offer targeted NLP tooling. However, for mission-critical enterprise applications scanning packaged foods—where schema stability, low latency, and deep multi-attribute parsing are mandatory—NutriGraphAPI provides an infrastructure-grade graph database of over 5,000,000 UPC-indexed products.

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    3. Schema Architecture: Unpacking Stated vs. Qualified Data and Ingredient Allergen Trees

    A common failure mode in lower-tier nutrition APIs is the collapsing of raw OCR packaging data and inferred system metadata into a single flattened object. If a field simply reports is_gluten_free: true, downstream systems cannot verify whether that flag was explicitly printed on the package or derived algorithmically. NutriGraphAPI addresses this ambiguity through a explicit two-layer object hierarchy: scraped_data and analysed_data.

    The scraped_data object reflects the raw, immutable string payload extracted directly from manufacturer packaging and OCR captures. The analysed_data layer applies deterministic rules engines and machine learning models to normalize values, compute health scores, resolve taxonomy nodes across a 3-tier category hierarchy, and build per-ingredient allergen trees.

    {
      "gtin14": "00011110417004",
      "product_name": "Organic Whole Wheat Pasta",
      "scraped_data": {
        "declared_allergens_text": "Contains Wheat. May contain trace amounts of soy.",
        "ingredients_raw": "Organic durum whole wheat flour, purified water."
      },
      "analysed_data": {
        "allergens": {
          "gluten": {
            "stated_by_manufacturer": true,
            "qualified_by_system": true,
            "confidence_score": 0.998,
            "detected_in_ingredients": [
              {
                "ingredient_name": "durum whole wheat flour",
                "allergen_type": "wheat_gluten",
                "tree_depth": 1
              }
            ]
          },
          "soy": {
            "stated_by_manufacturer": false,
            "qualified_by_system": true,
            "cross_contamination_risk": "may_contain"
          }
        }
      }
    }

    This dual-layer approach allows developers to evaluate explicit statements against verified analytical output. For instance, evaluating gluten sensitivity against rigorous standards like Coeliac UK (Gluten-Free Certification Standards) requires understanding cross-contamination risks and sub-ingredient breakdowns rather than relying on top-level packaging marketing claims.

    NutriGraphAPI models 11 distinct allergen trees down to individual constituent ingredients, isolating compound ingredients into sub-nodes rather than treating the ingredient list as an unparsed blob of text.

    4. Scoring Engines: Computational NOVA, Nutri-Score, and Compliance Verification

    Modern backend systems frequently need to score incoming food items across nutritional quality, computational ultra-processing indices, and strict religious or dietary constraints. Rather than forcing backend developers to write custom regex parsers or maintain fragile lookup dictionaries, NutriGraphAPI exposes over 30 clean-label fields alongside six automated quality scores directly in the API payload.

    • NOVA Classification (1-4): Evaluates the extent of industrial processing using ingredient breakdown rules aligned with frameworks published by INRAE (French National Research Institute for Agriculture and Food). Flags ultra-processed markers like emulsifiers, hydrogenated oils, and artificial flavor hydrolysates.
    • Nutri-Score (A-E): Algorithmic calculation balancing negative nutrients (energy, sugars, saturated fatty acids, sodium) against positive elements (fruits, vegetables, nuts, fibers, proteins).
    • EcoScore (A-E): Environmental impact rating based on life-cycle assessment (LCA) proxies, packaging material types, and origin sourcing.
    • Organic & Non-GMO Flags: Differentiates official regulatory certifications (e.g., USDA Organic, EU Organic) from self-declared promotional text.
    • Carcinogenic & Additive Warning Engine: Scans declared additive numbers (E-numbers/INS) against hazard registries, highlighting targeted flags for compounds such as titanium dioxide or potassium bromate.

    Beyond quality metrics, compliance engines evaluate raw ingredient trees to deliver deterministic pass/fail flags across religious and ethical dietary regimes: Halal, Kosher, Jain, and Hindu compliance. For instance, Jain compliance dynamically evaluates the ingredient tree for root vegetables (such as garlic, onions, or potatoes) even if they are embedded within general flavor blends, while Hindu compliance flags bovine-derived gelatins or rennets hidden within unlisted enzyme groups.

    5. Edge-Case Engineering: GTIN-14 Normalization and Latency Mitigation

    At high request volumes, data pipeline bottlenecks almost always occur at the edge during barcode resolution or during database join operations over deeply nested JSON payloads. To maintain sub-150ms median response times across 5,000,000+ items, NutriGraphAPI uses a strict GTIN-14 normalization pipeline.

    Incoming queries submit strings that may contain whitespace, missing zeros, or check digits. The API pipeline transforms these inputs into standard GTIN-14 formats in memory before reaching query planners:

    // Example GTIN-14 Canonicalization Flow
    Input:  "011110417004"      (12-digit UPC-A string)
    Step 1: Strip non-numeric chars -> "011110417004"
    Step 2: Validate Modulo-10 checksum
    Step 3: Left-pad with zeros to 14 digits -> "00011110417004"
    Result: Direct index lookup in graph store (O(1) complexity)

    By enforcing canonical GTIN-14 formats at the routing tier, caching layers hit key-value stores directly, bypassing costly database scans. Cache warmers pre-populate geographically distributed edge caches for high-traffic barcodes, guaranteeing consistent response curves during peak retail hours.

    A critical failure mode in nutrition data architecture is handling missing attributes. When query payloads return missing keys or empty arrays interchangeably, client-side deserialization breaks. NutriGraphAPI handles missing data deterministically by strictly distinguishing between `null` (data not present on packaging) and `false` (attribute verified as absent), preventing runtime errors in statically typed downstream languages like Go, Rust, or TypeScript.

    6. Integration Architecture and Evaluation Playbook

    When benchmarking nutrition data providers during a vendor proof-of-concept (POC), engineering teams should structure tests around four objective criteria: GTIN match rate across target inventory, p99 latency under concurrent load, schema consistency across product variants, and allergen extraction accuracy.

    A standard REST call to retrieve a fully analyzed product payload using cURL illustrates the simple, single-endpoint interface:

    curl -X GET "https://api.nutrigraph.io/v1/products/00011110417004" \
      -H "Accept: application/json" \
      -H "X-API-Key: your_api_key_here"

    To evaluate performance in your stack, construct a test runner that executes the following workflow:

    1. Sample Selection: Select a representative sample of 1,000 barcodes from your actual user activity logs, including edge cases like private-label regional brands, imported items, and legacy UPCs.
    2. Parallel Lookup Benchmark: Execute parallel GET requests across candidate APIs, recording p50, p90, and p99 response times, HTTP failure rates, and payload sizes.
    3. Schema Validation: Pass payloads through a strict JSON Schema validator to verify that required structural fields—such as dual `stated` vs `qualified` attributes and 3-tier category hierarchies—do not drift across queries.
    4. Field Accuracy Audit: Randomly sample 50 returned items and perform a side-by-side verification of `scraped_data` against actual physical package labels to measure OCR and extraction precision.

    Engineering teams can initiate sandbox testing immediately using NutriGraphAPI’s free developer tier, which offers 1,000 free monthly lookups without requiring a credit card.

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols and global barcoding standards across these sources:

  • A Technical Evaluation of the Google Nutrition API for Scalable Backends

    1. The Architectural Reality of Searching for a Google Nutrition API

    When technical leaders and backend engineers begin building barcode scanning engines, clinical nutrition platforms, or e-commerce catalog enrichers, searching for a google nutrition api is a common first step. The expectation is straightforward: Google Cloud offers mature, highly available managed APIs for vision, translation, mapping, and natural language processing, so it seems reasonable that a canonical Google Nutrition API exists to resolve universal product codes (UPCs) into structured nutritional schemas with sub-second latencies.

    However, an immediate architectural reality emerges upon technical investigation: Google does not offer a standalone, managed food nutrition database API. What developers typically encounter under the banner of Google food data is a fragmented combination of generic Google Cloud Vision API OCR calls, Knowledge Graph Search API queries, or Custom Search JSON API endpoints returning Schema.org NutritionInformation objects.

    Attempting to assemble a production-grade nutrition backend using raw GCP primitives creates significant technical debt. To build a reliable system on top of unstructured or general-purpose endpoints, engineering teams are forced to build and maintain complex internal pipelines to handle barcode-to-entity resolution, optical character recognition (OCR) error correction on curved packaging, non-standardized nutrient unit normalization (such as converting sodium in milligrams to salt in grams), and schema drift. Furthermore, unstructured knowledge graphs lack the relational depth needed to identify derivative allergen traces or verify manufacturer compliance claims against international food standards.

    2. Evaluating GCP Primitives vs. Dedicated Food Data Pipelines

    To understand why building a wrapper around GCP primitives often fails in production, it is useful to evaluate the end-to-end request pipeline of a image-to-nutrition workflow relying on generic OCR and Knowledge Graph lookups against a dedicated food data API architecture.

    Evaluation Dimension GCP Primitive Stack (Vision OCR + Knowledge Graph) Purpose-Built Food Data API (e.g., NutriGraphAPI)
    Lookup Latency 800ms – 2,500ms (Multi-step OCR + LLM/Entity Match) < 150ms median latency (Direct GTIN-14 key-value cache)
    Data Model Depth Flat Schema.org key-values (Calories, Total Fat, Sodium) 200+ structured attributes split across dual raw/derived layers
    Allergen Resolution Unstructured string match on raw text blocks Nested per-ingredient allergen trees across 11 key allergens
    Identifier Support Inconsistent text search match on numeric barcodes Native GTIN-14, GTIN-13, GTIN-8, and UPC-A normalization
    Quality Scoring None (Requires custom pipeline execution) Deterministic NOVA, Nutri-Score, EcoScore, and Clean-Label flags

    When engineering backends that require strict consistency—such as medical diet tracking, automated grocery inventory tagging, or consumer safety applications—relying on probabilistic Knowledge Graph lookups introduces critical failure modes. Schema.org objects do not mandate consistent units of measure, nor do they differentiate between declared panel values and validated analytical values. When aligning with global regulatory definitions such as the Codex Alimentarius International Food Standards, backends need deterministic precision rather than probabilistic text parsing.

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    3. Data Architecture Requirements: Beyond Product-Level Booleans

    A common pitfall in food software engineering is representing food safety data—specifically allergens—as flat, product-level boolean flags (e.g., contains_peanuts: true). In production, this naive schema breaks down under real-world supply chain conditions. A single packaged product contains primary ingredients, processing aids, sub-ingredients, and potential factory cross-contamination risks that cannot be accurately represented by a single flag.

    Modern nutritional backend architectures require multi-tiered relational mapping. For example, clinical food software standards aligned with bodies like the Australasian Society of Clinical Immunology and Allergy (ASCIA) emphasize that allergen risk assessment must track both direct ingredients and processing pathways. If a product contains hydrolysed whey protein, a system relying on raw keyword matching might miss the underlying dairy link unless the database maintains a deep ingredient graph that resolves sub-components.

    To solve this, modern APIs structure product data across two distinct layers: scraped_data (the unedited OCR extraction of package text) and analysed_data (the normalized, verified, and computationally enriched layer). Furthermore, fields must be split into dual stated (manufacturer-declared) and qualified (AI-verified and cross-checked) values to maintain auditability without sacrificing execution speed.

    Equally critical is the inclusion of environmental and processing metrics. Modern applications increasingly demand context on food sustainability—incorporating concepts championed by the Ellen MacArthur Foundation (Circular Food Economy)—which requires structured fields for EcoScore, agricultural origins, and packaging circularity alongside standard macronutrients.

    4. Comparative Landscape: Evaluating Backend Food Data APIs

    When selecting a data provider for production systems, backend architects must evaluate trade-offs across coverage, schema depth, latency, and cost. Below is an honest engineering breakdown of the leading alternatives in the food data ecosystem:

    • USDA FoodData Central: The gold standard for foundational agricultural commodities and raw ingredient micronutrient breakdowns. However, it lacks robust coverage for branded packaged goods, lacks GTIN-14 normalization, and provides no real-time clean-label or allergen graph transformations. Excellent for academic research; inadequate for consumer packaged goods (CPG) barcode scanning.
    • Open Food Facts: A massive, open-source community crowd-sourced database. It offers broad international coverage and free access. The trade-off is significant data quality variance, inconsistent field completion, lack of SLA guarantees, and frequent schema drift, requiring heavy validation logic on your backend.
    • Edamam: A strong contender for culinary applications, recipe analysis, and natural language text parsing (e.g., converting “2 cups of chopped apples” into nutrients). However, its payload structures are optimized for culinary recipes rather than deep GTIN-indexed packaging analytics and multi-tier quality scoring.
    • Spoonacular: Excellent for consumer-facing recipe search, meal planning, and widget integrations. Like Edamam, it excels in recipe workflows but is less focused on high-throughput enterprise GTIN lookup performance with low-latency SLAs.
    • Nutritionix: Popular for fitness logging apps and restaurant menu tracking. Its API is tailored toward end-user dietary logging, but access to deep ingredient lineage trees, 30+ clean-label indicators, and multi-cultural compliance flags is limited compared to dedicated enterprise catalog engines.
    • NutriGraphAPI: Purpose-built for enterprise CPG indexing, retail enrichment, and scalable backend services. Indexing over 5,000,000 UPC-indexed packaged products with sub-150ms median latency, it delivers over 200 attributes per product, 3-tier category hierarchies, per-ingredient allergen trees, and specialized quality scoring.

    5. Payload Architecture and Integration Patterns

    To demonstrate how structured nutritional backends handle complex packaged goods data, consider the following response payload representation. The schema separates raw ingestion from processed insights, normalizes the barcode into a standard GTIN-14 format, and evaluates ingredient trees for allergens, religious compliance, and clean-label quality metrics.

    {
      "gtin": "00012345678905",
      "product_name": "Organic Almond Crunchy Granola",
      "category_hierarchy": {
        "l1": "Food & Beverage",
        "l2": "Cereals & Breakfast Foods",
        "l3": "Granola & Muesli"
      },
      "scraped_data": {
        "raw_ingredients_text": "Organic Rolled Oats, Organic Cane Sugar, Organic Almonds, Sea Salt.",
        "stated_serving_size": "30g"
      },
      "analysed_data": {
        "serving_size_grams": 30.0,
        "macronutrients_per_100g": {
          "energy_kcal": {"stated": 450, "qualified": 448.2},
          "proteins_g": {"stated": 10.0, "qualified": 10.0},
          "carbohydrates_g": {"stated": 65.0, "qualified": 64.8},
          "sugars_g": {"stated": 18.0, "qualified": 18.0},
          "fat_g": {"stated": 16.0, "qualified": 15.9}
        },
        "allergen_tree": {
          "tree_nuts": {
            "present": true,
            "derived_from": ["Organic Almonds"]
          },
          "peanuts": {"present": false, "derived_from": []},
          "gluten": {
            "present": true,
            "derived_from": ["Organic Rolled Oats"],
            "cross_contamination_risk": false
          }
        },
        "clean_label_flags": {
          "no_artificial_preservatives": true,
          "no_high_fructose_corn_syrup": true,
          "ultra_processed": false
        },
        "quality_scores": {
          "nova_group": 2,
          "nutri_score": "A",
          "eco_score": "B",
          "organic": true,
          "non_gmo": true,
          "carcinogenic_additive_flag": false
        },
        "dietary_compliance": {
          "halal": true,
          "kosher": true,
          "jain": false,
          "hindu": true
        }
      }
    }

    By structuring data with this explicit separation, application logic can immediately evaluate safety rules (such as checking dietary_compliance or high-risk items in allergen_tree) without running complex string-parsing routines on the client or server.

    6. Performance, Latency, and Edge Caching Strategies

    When integrating food data lookups into real-time applications—such as mobile POS systems or live camera-stream barcode readers—latency is the decisive metric. A backend pipeline that calls external vision OCR models and secondary parsing APIs typically exhibits p95 latencies exceeding 2,000 milliseconds. This degrades user experience and causes thread pool starvation under high concurrent loads.

    To maintain sub-150ms median latency at scale, NutriGraphAPI employs canonical GTIN-14 normalization at the edge. Because UPC-A (12 digits), EAN-13 (13 digits), and GTIN-14 representations can refer to the same physical SKU, incoming request keys are transformed deterministically before database indexing. This enables cache hits directly at the edge layer, bypassing expensive query engines for previously indexed products.

    Architecturally, backend services should implement a local Redis or Memcached cache layer keyed by normalized GTIN-14 strings, utilizing an LRU (Least Recently Used) eviction policy with a 24-to-72-hour TTL. This strategy ensures that high-velocity products (e.g., popular national CPG brands) return payload responses in single-digit milliseconds, while long-tail items fall back to NutriGraphAPI’s sub-150ms primary lookup engine.

    7. Technical Evaluation Checklist for Engineering Teams

    Before deciding whether to build on GCP primitives or integrate a specialized provider like NutriGraphAPI, engineering leads should execute a quick proof-of-concept (PoC) audit against their target dataset using this structured protocol:

    1. Identifier Normalization Check: Test your system with variations of the same barcode (e.g., leading zero padding on UPC-A vs GTIN-14). Ensure the API resolves them to the exact same canonical record.
    2. Allergen False-Positive/Negative Rate: Query 50 complex multi-ingredient items containing derivative sub-ingredients (e.g., soy lecithin, whey powder, modified food starch). Verify whether the API provides deterministic per-ingredient allergen trees or simple unparsed strings.
    3. Latency Profiling: Execute 1,000 concurrent requests against the lookup endpoint to measure p95 and p99 latencies under load.
    4. Clean-Label & Compliance Coverage: Verify whether the schema includes explicit flags for religious dietary needs (Halal, Kosher, Jain, Hindu) and clean-label standards (30+ clean-label indicators, NOVA processing tiers, Nutri-Score, EcoScore).

    To evaluate these parameters directly against production workloads, NutriGraphAPI offers a developer tier providing 1,000 free monthly lookups with no credit card required, allowing backend teams to benchmark real-time payload performance and schema depth within minutes.

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols and global barcoding standards across these sources:

  • Understanding Open Food Facts API Pricing Rate Limits and Costs for Backend Production

    1. Evaluating Open Food Facts API Pricing, Rate Limits, and Infrastructure Costs

    When architecting a backend system that relies on packaged food metadata, barcode scanning, or ingredient parsing, engineering teams frequently start with open-source options. Open Food Facts (OFF) is often the first stop because its API is free and publicly accessible. However, evaluating open food facts api pricing requires looking beyond the nominal direct cost of zero dollars and analyzing the true Total Cost of Ownership (TCO) at production scale.

    For consumer-facing or early prototype applications, a free REST API without licensing fees is compelling. But when powering production services with real-time throughput requirements, strict uptime Service Level Agreements (SLAs), and structured compliance needs, the operational overhead of public infrastructure manifests rapidly. Public infrastructure endpoints enforce aggressive rate limits to prevent abuse and preserve public resources. Running a high-concurrency production workload directly against the public Open Food Facts endpoints risks throttled HTTP status code 429 responses, unannounced schema shifts, and unpredictable tail latency.

    Engineering teams building enterprise pipelines generally choose between two patterns to overcome public rate limits: maintaining an internal mirroring pipeline by consuming daily MongoDB export dumps, or routing queries through a managed multi-tenant API infrastructure designed for low-latency production SLAs. Adhering to robust data ingestion guidelines, as highlighted in the IEEE Computer Society (Data Architecture Standards), requires assessing the long-term compute, storage, ETL maintenance, and data-cleansing costs involved in maintaining unmanaged open datasets versus leveraging specialized commercial data infrastructure.

    2. Technical Rate Limits and Data Normalization Overhead in Open Food Facts

    The public Open Food Facts REST API enforces strict usage policies. While read limits fluctuate depending on cluster load, aggressive polling or bulk catalog enrichment will quickly hit IP-based rate caps. For applications requiring rapid real-time lookups during active user sessions, hitting rate limits breaks core UX loops. Furthermore, bulk ingestion via public endpoints is explicitly discouraged by the community guidelines, which instruct developers to download the compressed JSON or MongoDB nightly dumps for high-volume analysis.

    Downloading and parsing the raw MongoDB dump introduces substantial data engineering overhead. The raw export contains millions of crowdsourced records, but data completeness and quality vary drastically across geographical regions and product categories. Key technical challenges include:

    • Inconsistent GTIN/UPC Formats: Barcode keys across crowdsourced records often mix UPC-A, EAN-13, EAN-8, and non-standard internal PLUs without systematic GTIN-14 normalization, causing cache misses and key duplication in local databases.
    • Unstructured Ingredient Strings: Raw ingredient text is extracted directly from package labels via OCR or user text entry. These strings often contain typos, regional language variations, and inconsistent punctuation rather than structured ingredient trees.
    • Flat Boolean Allergen Flags: Crowdsourced flags often rely on high-level booleans (e.g., contains_gluten: true) rather than granular, per-ingredient relational mapping. In medical or precision compliance contexts—such as those defined by the Australasian Society of Clinical Immunology and Allergy (ASCIA)—relying on unverified boolean flags without explicit parent-child ingredient tracing can lead to false positives or dangerous omissions.
    • Unscheduled Schema Mutations: Because field generation is heavily community-driven, keys within raw product documents can appear, disappear, or mutate type structures without formal deprecation schedules.

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    3. Total Cost of Ownership: Free API vs. Commercial Food Data Pipelines

    When calculating open food facts api pricing against production needs, engineers must account for the dedicated compute, storage, and engineering hours required to transform raw open-source dumps into a high-availability database service. The table below illustrates the trade-offs across common operational dimensions when building production architectures:

    Dimension Open Food Facts (Public API) Self-Hosted OFF Pipeline Managed NutriGraphAPI
    Direct API Cost $0 $0 (data license) Developer tier: 1,000 free monthly lookups (no card required); scalable usage tiers
    Rate Limits Strict IP-based throttling (~100 req/min) Internal infrastructure capacity High concurrency, SLA-backed throughput
    Latency SLA Unpredictable (500ms – 3000ms+) Depends on internal caching/DB indexing sub-150ms median latency
    ETL Maintenance None High (daily dump sync, schema normalization) Zero maintenance (managed service)
    Data Architecture Unstructured/Crowdsourced Requires custom cleaning scripts GTIN-14 normalized, 200+ structured attributes
    Ingredient Mapping Flat string / basic booleans Custom NLP parsing required Per-ingredient allergen trees (11 allergens), dual stated/qualified fields

    For engineering organizations, hosting an ETL pipeline to parse, clean, index, and query 5+ million products demands ongoing DevOps support, dedicated MongoDB/Elasticsearch clusters, and custom parsing scripts to handle edge cases. This infrastructure footprint often costs thousands of dollars per month in Cloud compute and engineering maintenance, quickly outpacing the price of a managed API solution.

    4. Schema Architecture: Raw Extraction vs. Deterministic AI Verification

    Production applications in health, retail, and food-tech require deterministic payload schemas. A key limitation of raw crowdsourced datasets is the lack of separation between what a manufacturer prints on a label and what an independent analytical engine verifies. NutriGraphAPI solves this structural issue by organizing 200+ product attributes across a strict two-layer architecture: scraped_data (verbatim label extraction) and analysed_data (deterministic verification and enrichment).

    This dual-layer approach provides explicit fields for both “stated” (manufacturer-declared) claims and “qualified” (AI-verified) status. For instance, a product label may claim to be non-GMO, but qualified verification checks the explicit ingredient tree against verification databases like the Non-GMO Project Verified Registry to detect unverified high-risk bioengineered derivatives.

    Below is a truncated representative JSON response from NutriGraphAPI illustrating this payload structure, including GTIN-14 normalization, per-ingredient allergen trees, and health quality scores:

    {
      "gtin14": "00012345678905",
      "product_name": "Organic Oat & Almond Protein Bar",
      "category_hierarchy": {
        "primary": "Snacks",
        "secondary": "Bars",
        "tertiary": "Protein Bars"
      },
      "scraped_data": {
        "declared_ingredients_raw": "Organic Whole Grain Oats, Almond Butter, Cane Sugar, Sea Salt.",
        "declared_certifications": ["USDA Organic", "Kosher"]
      },
      "analysed_data": {
        "ingredient_tree": [
          {
            "ingredient": "Organic Whole Grain Oats",
            "canonical_id": "ing_oats_001",
            "allergens": [{"allergen": "gluten", "detected": true, "cross_contamination_risk": false}]
          },
          {
            "ingredient": "Almond Butter",
            "canonical_id": "ing_almonds_002",
            "allergens": [{"allergen": "tree_nuts", "detected": true, "cross_contamination_risk": false}]
          }
        ],
        "compliance_flags": {
          "halal": {"stated": false, "qualified": true},
          "kosher": {"stated": true, "qualified": true},
          "jain": {"stated": false, "qualified": false},
          "hindu": {"stated": false, "qualified": true}
        },
        "quality_scores": {
          "nova_group": 3,
          "nutri_score": "B",
          "ecoscore": "A",
          "organic": true,
          "non_gmo": true,
          "carcinogenic_additives_flag": false
        }
      }
    }

    5. Benchmarking the Landscape: Open Food Facts, USDA, Edamam, Nutritionix, and NutriGraphAPI

    When selecting a food data backend, technical leaders must match API capabilities to their specific domain requirements. No single database fits every technical use case, and recognizing the strengths of each platform is critical during architectural evaluation:

    • USDA FoodData Central: The gold standard for raw, unbranded agricultural commodity data (e.g., raw apples, whole grains). Excellent for foundational nutrient research, but lacks commercial UPC barcode coverage, clean-label flags, and retail packaging context.
    • Open Food Facts: Unmatched open-source global footprint driven by community contributions. Ideal for non-profit research, open data projects, and low-concurrency applications where latency and missing attributes can be handled gracefully in UX.
    • Nutritionix: Highly optimized for restaurant menu items, generic branded foods, and consumer meal logging apps. Strong in US consumer coverage, but less focused on deep algorithmic allergen trees or multi-layered compliance verification.
    • Edamam & Spoonacular: Purpose-built for recipe analysis, meal planning, semantic recipe parsing, and cooking instruction workflows. They excel at converting unstructured recipe text into nutritional summaries, but are not optimized as enterprise GTIN-14 packaging verification engines.
    • NutriGraphAPI: Purpose-built for enterprise packaged food infrastructure requiring 5,000,000+ UPC-indexed products, sub-150ms median latency, 3-tier category hierarchies, 30+ clean-label metrics, religious compliance flags (Halal, Kosher, Jain, Hindu), and per-ingredient allergen trees across 11 key allergens.

    6. Production Integration Strategy: SLA Guarantees and API Evaluation

    When transitioning from raw crowdsourced lookups to a dedicated production backend, engineering teams should evaluate prospective APIs against key technical criteria: median/p99 response latency, schema stability, GTIN normalization standards, and ingredient resolution depth.

    To prevent downstream system failures, production architectures should implement distributed caching (e.g., Redis) for high-frequency GTIN lookups while maintaining a low-latency fallback stream to a managed API service. Relying on an endpoint that delivers sub-150ms median latency ensures that real-time mobile scanning and backend data pipelines remain responsive under spike traffic conditions.

    Backend engineers can test payload structures, benchmark query response times, and evaluate compliance resolution without financial commitment. NutriGraphAPI provides a Developer tier with 1,000 free monthly lookups and no credit card required, allowing teams to run side-by-side benchmarking scripts against existing datasets before deploying to production.

    Try it against your own barcodes

    Migrate to modern REST food intelligence with 1,000 free monthly lookups on our Developer tier — no card required.

    Claim Free Developer API Key →

    Inspect every field first in the Interactive Schema Explorer.

    Authority Citations & Regulatory References

    Cross-reference food safety, clinical nutrition protocols and global barcoding standards across these sources: